
Estimated reading time : 4 min · Published
Choose the journey to protect
Describe the essential action, audience and dependencies that can interrupt it. A business site may need visitors to read an offer and send enquiries; a shop needs correctly recorded orders. Separate page loading, action completion and subsequent handling because these steps can fail differently.
The Google SRE Workbook describes service objectives based on indicators and agreement between stakeholders. Adapt the approach to the site’s size. A small team can start with one journey, an observable indicator and an owner rather than many dashboards without associated decisions.
Define events and observation windows
Write what counts as an attempt and success, where it is observed and which exclusions are justified. Deliberately invalid input differs from loss of a valid enquiry. Synthetic monitoring and actual usage observe different populations; keep their results separate.
Define the reading window and minimum useful evidence. Percentages are unstable with few events on a low-traffic site. Show attempt and failure counts alongside the rate and investigate reproducible cases. Avoid collecting unnecessary messages or personal information to measure a technical outcome.
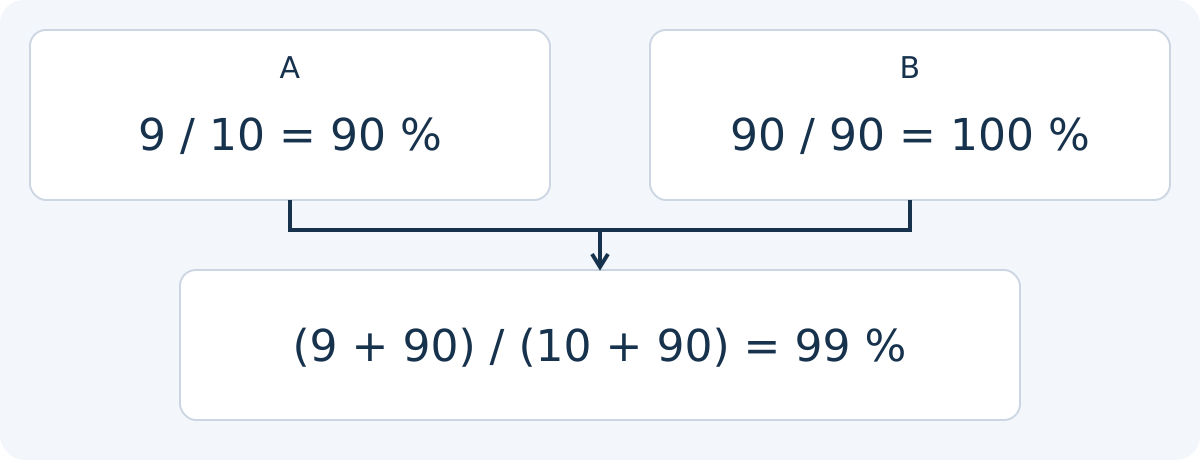
Retain counts when aggregating an event-based indicator. Fictional example: group A has 9 successes from 10 attempts, or 90%; group B has 90 from 90, or 100%. If groups are disjoint, cover the same period and use the same success definition, the total is (9 + 90) / (10 + 90) = 99%. The simple average (90 + 100) / 2 = 95% describes a mean of group rates, not the success rate of these 100 attempts.
The SRE Workbook presents indicators as good events divided by all selected events. Before adding counts, check deduplication, window, exclusions and attempt definition: a retry can be another event without being a new visitor request. Retain group rates when the total hides a local obstacle. With no observed attempt, the rate is undefined; interrupted collection is a coverage limit, not evidence of zero failures. These ratios do not automatically measure time-based availability.
Scroll the table horizontally to read every column. With a keyboard, focus the table area and use the arrow keys.
| Population or calculation | Successes / attempts | Interpretation |
|---|---|---|
| Group A | 9 / 10 | 90 % |
| Group B | 90 / 90 | 100 % |
| Total attempts | 99 / 100 | 99 % |
| Simple mean of the two rates | (90 + 100) / 2 = 95 % | Equal weight for groups, not for attempts |
Choose an objective before making a commitment
An internal objective describes a desired level and guides decisions. A contractual commitment has scope and consequences requiring separate agreement. Avoid adopting a high percentage merely because it sounds reassuring. Compare visitor needs, operating constraints and recovery costs.
In a fictional calculation, 10 failures among 1,000 attempts produce 99% success. This does not describe duration, affected people or severity: identical counts can represent minor inconvenience or lost orders. Time-based availability requires a different definition; do not convert indicators without explaining the method.
Connect thresholds to actions
Decide who investigates alerts, what evidence establishes an incident and how affected people are informed. A confirmed outage may require a workaround or rollback. An isolated alert may need verification before escalation. Reduce uncertainty and response time rather than generating messages for every fluctuation.
Document quality declines during changes. The error-budget policy chapter describes agreed responses to reliability gaps. A small site might simply delay an optional change until a critical defect is resolved without claiming to implement a large service’s operating model.
Verify observers and review incidents
Test monitoring itself: does it distinguish page availability from completed actions? Can it detect a lost notification? Does it issue an understandable alert that receives a response? Disruptive scenarios belong in authorised environments. Production checks must avoid fictional orders and accidental messages.
After incidents, connect timelines, impact, fixes and regression checks. Revise indicators if faults escaped detection. The incident-response guide and pre-publication checks help assign actions and retain findings. Useful objectives evolve with journeys and observed risks.
Check returning to a list after a detail page and guard against stale state.
Synthetic case: someone filters a list, opens a detail page and presses Back. Check useful filter preservation and freshness of sensitive elements after restoration. The bfcache differs from HTTP cache: one header alone does not establish its behaviour. Do not weaken private-page safeguards simply to improve a navigation score.
- Returning preserves useful context and information requiring refresh follows a tested rule.
- web.dev Back/forward Cache
Explanation of back/forward navigation cache, which may restore a page and its state without a full reload.
Reference documents
- Google SRE Workbook · Source consulted
- error-budget policy chapter
- web.dev Back/forward Cache · Source consulted
Content updated on