
Estimated reading time : 7 min · Published
Move from an available copy to a usable website
Having a backup and successfully restoring it are different findings. Plan checks on an isolated copy before deciding on production work.
- Identified copy
Version, date and scope are known.
- Isolated restoration
Required components are restored away from production.
- Checks
Inspect agreed pages, media, data and journeys.
- Review
Record outcomes, limitations and the recovery decision.
Fictional teaching scenarios to adapt to your system. This page performs no operation on your website.
Open the situation you want to check
The archive exists but has never been restored
- What is known
- A copy is available; its usability is not yet demonstrated.
- The next check
- Prepare a trial with required dependencies and record what is needed to recover a usable service.
The homepage opens, but media is missing
- What is known
- Initial access works; the restored scope remains incomplete.
- The next check
- Check media files, paths, permissions and dependencies before declaring the site restored.
The copy could send real messages
- What is known
- A test could affect production services.
- The next check
- Isolate sending and integrations before testing, then inspect journeys using demonstration data.
Files and data carry different versions
- What is known
- The copy’s files are labelled V2 and its database V1. A page opening does not establish compatibility.
- The next check
- Compare the intended recovery scope with restored versions and replay a journey that reads then saves fictional data. Classify gaps before any production decision.
- Evidence to retain
- Each component’s version and date, expected dependencies, test value before/after and observed limits; no configuration secrets.
Technical reference : Cybermalveillance.gouv.fr · Sauvegardes · Consulted .
Define what must be recoverable
Inventory code, content, databases, uploads, media, application settings and scheduled jobs. Some elements live with the host, others in a CMS, separate storage or a third-party service. Distinguish what can be rebuilt from what would be lost permanently.
Set an acceptable recovery point for each set: a brochure site updated monthly and a service receiving daily enquiries have different needs. Record copy frequency, location, retention and who can initiate a restoration.
- Inventory of necessary content and data.
- Acceptable recovery point for each set.
- Copy locations and accountable people.
Separate copies, exports and restoration
An editorial export may retrieve text but omit themes, settings, users or media. Files alone may omit the database. Ask the provider exactly what its service covers and what remains your responsibility. WordPress documentation recommends backing up before plugin updates; the exact method depends on the architecture.
Protect copies according to the context and limit who can read or replace them. Document restoration prerequisites without publishing credentials, keys or access details in a shared guide.
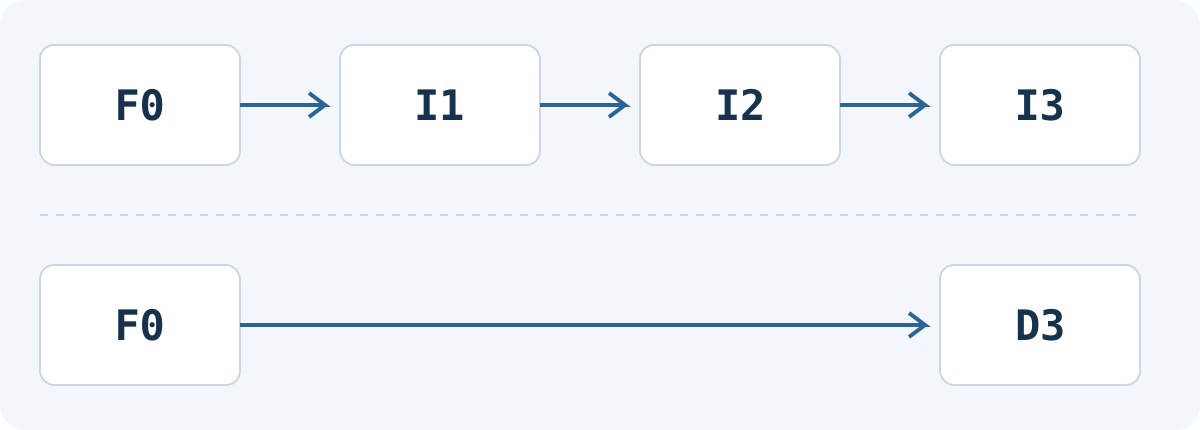
Identify dependencies before selecting the newest archive. In NIST’s classic model, a full backup covers the selected scope, an incremental contains changes since the previous backup and a differential changes since the last full backup. In this exercise F0 is the starting full copy; I1, I2 and I3 are successive incrementals. Finding I3 alone cannot reconstruct that scope at the third point.
The differential branch is an alternative strategy: D3 accumulates changes since F0, so this model uses F0 and D3 without intermediate differentials. These are teaching dependencies, not archives available on this site. Deduplicated, synthetic or snapshot-based tools may behave differently; check the provider’s contract. Retention must preserve what retained restore points require, and authorised people must be able to access the necessary keys.
Scroll the table horizontally to read every column. With a keyboard, focus the table area and use the arrow keys.
| Exercise strategy | Set examined in the exercise | Limit to check |
|---|---|---|
| Initial full backup alone | F0 | Starting point only; no later changes |
| Successive incrementals through I3 | F0 + I1 + I2 + I3 | Every intermediate dependency is required |
| Differential D3 since F0 | F0 + D3 | Alternative branch; D1 and D2 not needed here |
| I2 missing from incremental chain | F0 + I1 + I3 | Incomplete chain for point I3 in this exercise |
Rehearse in an isolated environment
Choose a copy and restore it away from the public website. Time the steps instead of assuming the written procedure is complete. Check pages, media, links, required permissions, the form in test mode and functions that rely on external services.
Compare restored data with the initial inventory. Record absent items, the latest change present and settings that need rebuilding. A successful exercise should be repeatable by another authorised person within the time the organisation considers acceptable.
Fictional rehearsal in an isolated environment: the expected backup contains 120 articles and 200 identified media items. Restoration finds 120 articles and 200 media items, but M200 is missing and X200, absent from the expected inventory, replaces it. Equal counts conceal a mismatch: only 199 expected media identifiers are present. Compare identifier sets before inspecting the affected files and links.
The table separates four checks. Even if articles, test roles and the contact journey pass, the media mismatch prevents acceptance of the complete rehearsal. The three roles are fictional profiles checked against a defined permissions matrix. The form uses a test enquiry and a neutralized email sink; no real delivery is required to check the planned chain in this environment.
- Copy and environment used.
- Observed duration and manual steps.
- Pages, data and functions actually checked.
Scroll the table horizontally to read every column. With a keyboard, focus the table area and use the arrow keys.
| Checked set | Test observation | Acceptance decision |
|---|---|---|
| Articles | 120 expected, 120 recovered, matching identifiers | Identifiers match; values and links are not covered by this check alone. |
| Media | 200 expected, 200 recovered; M200 missing, X200 unexpected | Failed: fix the mismatch and repeat the checks |
| Test roles | 3 profiles with permissions matching the matrix | Planned check passed; no claim about other access |
| Contact journey | 1 enquiry saved and notification received by the test sink | Test chain passed; overall restoration not yet accepted |
- Cybermalveillance.gouv.fr : Sauvegardes
Cybermalveillance.gouv.fr, consulted 22 October 2026: testing backups. The volumes, identifiers and results are fictional.
Fix the plan and schedule the next exercise
Update the procedure after each rehearsal: contacts, operation order, dependencies and exit checks. Repeat after a migration, provider change or significant application update. The maintenance guide puts restoration checks into regular site operations.
During a real incident, preserve useful diagnostic information and coordinate recovery with the responsible people. A restoration test reduces uncertainty; it does not guarantee zero loss or a third party’s availability.
Decide in a concrete situation
Fictional example: the database is recovered but media are missing and accounts fail. Define restored service before testing: data, files, access and essential functions need examination together.
Record backup point, isolated environment, steps and journey result. Retain missing elements and observed time; archive size does not establish that operations can resume.
- Protect and test a website staging environment
Separate access control from indexing, prevent real messages and transactions, use synthetic data and verify the production transition.
Measure acceptable loss and recovery time separately
Define both the maximum age of data you can afford to lose and the acceptable interruption. A daily copy does not guarantee fast recovery: domain control, access, secrets or dependencies may be missing. Measure both gaps during a restore exercise.
Calculate the gap between the backup point and service recovery
Fictional exercise on the same day and in the same time zone: last usable backup at 02:00, incident at 10:30, verified service at 12:00. Assume that no log or other mechanism recovers changes made after the copy.
Scroll the table horizontally to read every column. With a keyboard, focus the table area and use the arrow keys.
| Reference point | Exercise calculation | Interpretation |
|---|---|---|
| Age of recovered data | 10:30 − 02:00 = 8 h 30 min. | Up to 8 h 30 min of changes are exposed to loss; their volume still needs examination. |
| Observed interruption | 12:00 − 10:30 = 1 h 30 min. | Measure recovery of the agreed service, not just completion of a file copy. |
| Fictional targets: RPO 4 h, RTO 2 h | 8 h 30 min > 4 h; 1 h 30 min ≤ 2 h. | The data objective is missed; the duration objective is met in this scenario only. |
- NIST · Recovery Point Objective
NIST defines RPO by the data recovery point and RTO by the recovery duration tolerable for business activity. These figures are teaching assumptions, not hosting guarantees.
Reference documents
- Cybermalveillance.gouv.fr : Sauvegardes · Source consulted
- NIST · Recovery Point Objective · Source consulted
- NIST · Recovery Time Objective · Source consulted
- NIST SP 800-34 Rev. 1 : Backup methods and plan maintenance · Source consulted
- WordPress documentation
Content updated on
Documented reference points for this topic
| Reference | Value or syntax | Scope |
|---|---|---|
| GitHub Docs · Repository backup | git clone --mirror | A mirror clone backs up the Git repository and its history. Git LFS objects require an additional fetch, and a wiki has its own repository. For a handover, also inventory data and services that do not reside in Git. |
Dates indicate when references were consulted. These facts are neither a site audit nor an overall compliance statement.