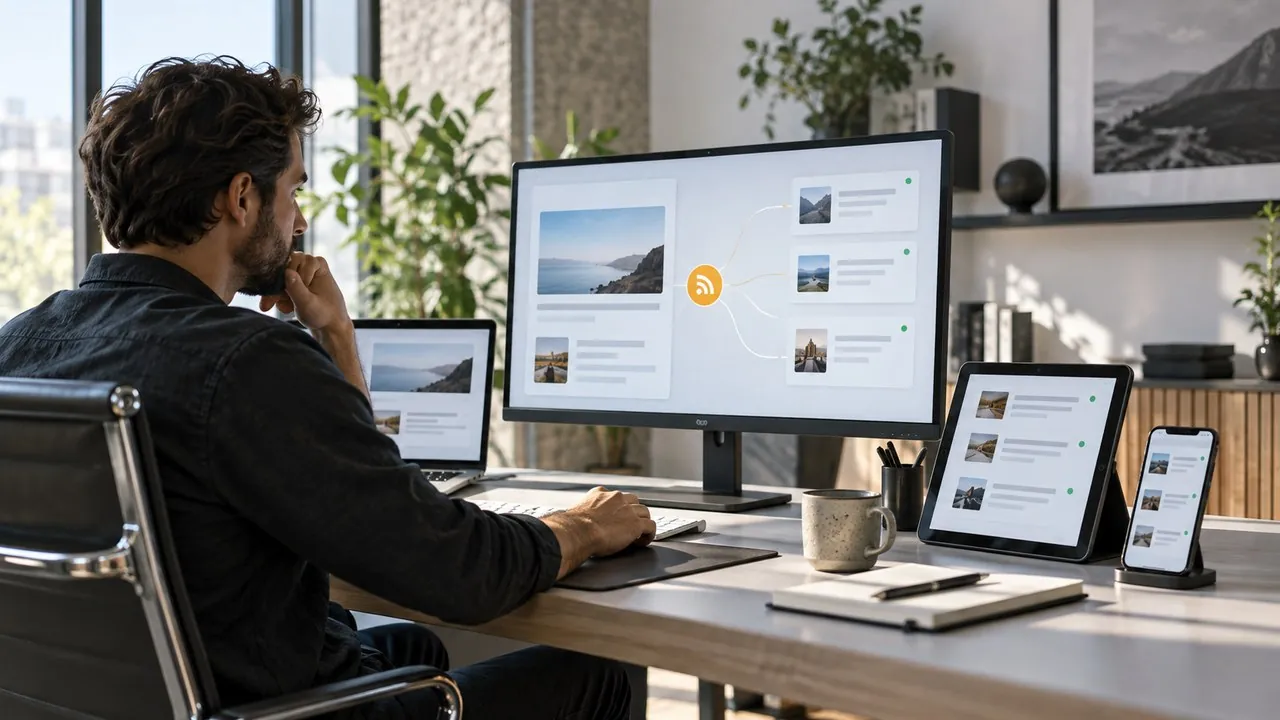
A useful RSS feed needs no request-time generation. Title, first paragraph, canonical URL, category and date are enough, removing cost, latency and API failure.
The useful answer depends on the purpose of the page, the people allowed to edit it and the cost of an error. A reliable workflow separates editorial decisions, technical delivery and final verification instead of hiding all three inside one automated operation.
The decision to make first
The feed should reflect reviewed content. A local rule can combine title and excerpt and apply network-specific character limits.
A practical method
- Read the same JSON as the pages.
- Strip HTML and leftover Markdown links.
- Use absolute URLs and stable GUIDs.
- Create valid RSS dates from editorial dates.
- Advertise the feed in the HTML head.
Checks before publishing
- The source of truth is explicit and can be restored.
- URLs, dates and visible claims match the delivered page.
- A human reviewer can reproduce the check without a hidden service.
The main pitfall
Random GUIDs or newly calculated dates make aggregators treat an old item as new on every request.
Recommended next step
Parse XML locally and test the public URL in a reader before connecting automation.
A controlled editorial feed
A site publishes four approved articles in a week. Its RSS feed uses the same IDs, titles, canonical URLs and publication dates as the pages. Descriptions summarise visible content; they are not generated independently on every feed request.
Open the XML, check all four links and confirm that dates have not become the last export time. Drafts and retired pages must stay out. When correcting an article, retain its feed ID and update its modification date when the change warrants it.